
About
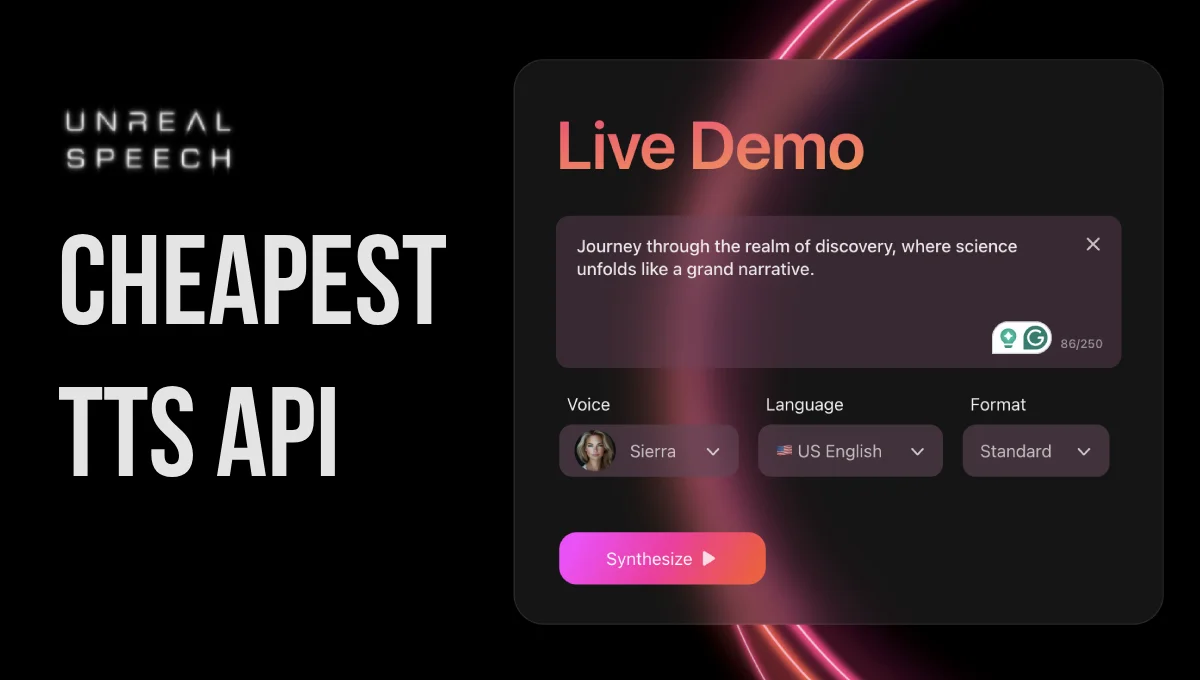
Unreal Speech is a developer-first text-to-speech API engineered for speed, quality, and affordability. It positions itself as up to 11x cheaper than ElevenLabs while delivering production-grade reliability with 99.9% uptime and sub-300ms audio streaming. The platform supports generating audio up to 10 hours in a single request, making it suitable for long-form content like audiobooks, podcasts, and e-learning modules. The API offers three core endpoints: `/stream` for instant synchronous responses on short text (up to 1,000 characters), `/speech` for medium-length content with timestamp support (up to 3,000 characters), and `/synthesisTasks` for asynchronous large-scale synthesis (up to 500,000 characters). A fourth endpoint, `/streamWithTimestamps`, enables real-time audio and per-word timestamp delivery via WebSocket — ideal for synchronized highlighting in reading or learning apps. With 48 available voices, 8 language options, adjustable speed and pitch, and multiple bitrate formats, Unreal Speech gives developers fine-grained control over output. Python SDK and REST API support make integration straightforward. The free tier includes 250,000 characters, with pricing that decreases as usage scales. It is trusted by high-volume customers processing 10,000+ pages per hour, demonstrating enterprise-grade scalability.
Key Features
- Ultra-Low Latency Streaming: Stream audio back in as little as 300ms via the /stream endpoint, enabling real-time voice experiences in apps and products.
- Per-Word Timestamps: Get precise word- or sentence-level timestamps alongside audio, perfect for synchronized text highlighting in reading or learning applications.
- Long-Form Audio Generation: Generate audio files up to 10 hours long in a single API request using the asynchronous /synthesisTasks endpoint (up to 500,000 characters).
- 48 Voices Across 8 Languages: Choose from a diverse library of 48 high-quality voices spanning 8 languages, with adjustable speed, pitch, and audio bitrate.
- Volume-Based Pricing: Start free with 250,000 characters and pay less per character as usage scales — designed to reward high-volume production workloads.
Use Cases
- Converting long-form articles, blog posts, or books into high-quality audio for audiobook or podcast platforms at scale.
- Adding synchronized read-along highlighting to e-learning apps using per-word timestamps streamed via WebSocket.
- Powering voice-enabled SaaS features (notifications, narrations, IVR) with low-latency audio streaming.
- Processing thousands of document pages per hour into audio files for accessibility tools or content aggregators.
- Replacing expensive TTS providers in existing production pipelines to dramatically reduce infrastructure costs.
Pros
- Extremely Cost-Effective: Significantly cheaper than competitors like ElevenLabs, Play.ht, and Amazon Polly, with discounts that grow as usage increases.
- Developer-Friendly API: Clean REST API with a Python SDK, multiple endpoints for different use cases, and clear documentation with ready-to-run code samples.
- Enterprise-Grade Reliability: 99.9% uptime and proven scalability processing billions of characters per month, including 10,000+ page-per-hour workloads.
- Generous Free Tier: 250,000 free characters allow developers to fully evaluate the API in production scenarios before committing to a paid plan.
Cons
- Limited Language Support: With only 8 supported languages, teams building multilingual global products may find coverage insufficient compared to some competitors.
- No Native Mobile SDKs: Official SDKs are currently limited to Python; mobile developers on iOS or Android must integrate via REST API directly.
- Voice Customization Constraints: Unlike some competitors, Unreal Speech does not currently offer voice cloning or custom voice creation features.
Frequently Asked Questions
How much does Unreal Speech cost?
Unreal Speech offers 250,000 characters for free. Beyond that, pricing scales based on usage volume and is consistently lower than competitors — claimed to be up to 11x cheaper than ElevenLabs at comparable tiers.
How fast does Unreal Speech generate audio?
The /stream endpoint delivers audio in approximately 300ms, making it suitable for real-time applications. The /speech endpoint takes roughly 1 second per 700 characters, and /synthesisTasks processes about 800 characters per second asynchronously.
Does Unreal Speech support per-word timestamps?
Yes. You can request word- or sentence-level timestamps via the /speech and /synthesisTasks endpoints, or stream both audio and timestamps simultaneously using the /streamWithTimestamps WebSocket endpoint.
What is the maximum audio length I can generate?
Using the /synthesisTasks endpoint, you can generate up to 500,000 characters in a single request, which equates to approximately 10 hours of audio.
What programming languages and platforms are supported?
Unreal Speech provides a Python SDK and a REST API accessible from any language or platform. Integration is straightforward via standard HTTP requests with Bearer token authentication.